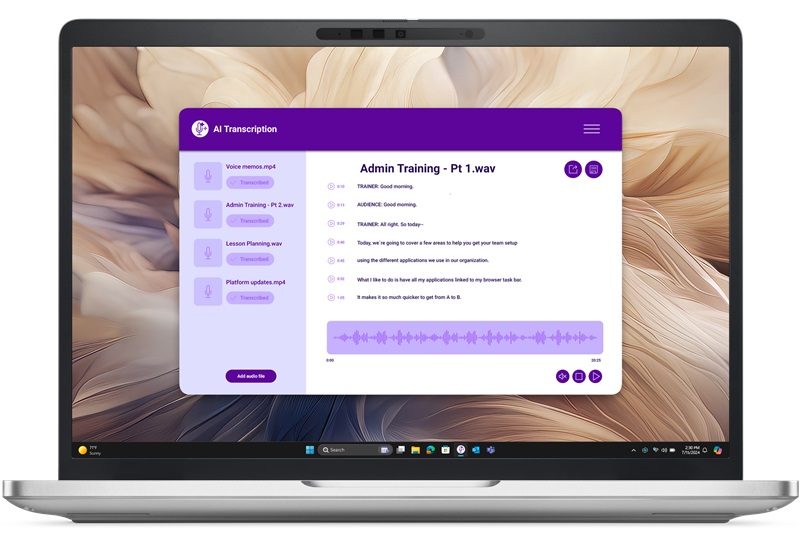

Transcribing audio files means converting recorded speech from meetings, interviews, lectures, or voice notes into written text. With modern tools, you can turn audio files into accurate transcripts much faster than manual typing.
This guide explains the best ways to transcribe audio files, how to choose the right tool, and practical steps for high-quality results. It focuses on the main keyword 音声ファイル 文字起こし and related audio file transcription needs.
Quick answer: To transcribe an audio file, upload it to a transcription tool that supports its format (most accept MP3, WAV, M4A and often video files such as MP4), choose the spoken language, start the transcription and then proofread the result while listening. If a file is too large or in an unusual format, convert or compress it first, and export the transcript as text, a Word document or subtitles depending on how you will use it.
What Does It Mean to Transcribe Audio Files?
Transcribing audio files is the process of taking an existing recording (such as MP3, WAV, or M4A) and generating a text version of the spoken content. The resulting transcript can be edited, searched, shared, or archived.
Common sources of audio files include:
- Meeting recordings
- Interview recordings
- Class lectures
- Podcast episodes
- Voice memos
- Customer support calls
Best Ways to Transcribe Audio Files
- AI Transcription Services
Upload your audio file to an online tool that automatically generates a transcript. This is the fastest method for most users.
- Desktop Transcription Software
Install software on your computer to process audio files locally or through the cloud.
- Speech-to-Text APIs
Developers and advanced users can integrate transcription directly into workflows.
- Manual Transcription
Listen and type. This is time-consuming but useful for highly sensitive or complex audio.
Step-by-Step Process to Transcribe an Audio File
- Prepare a clear audio file in a supported format.
- Choose a transcription tool.
- Upload the audio file.
- Select the correct language and any available settings.
- Start the transcription.
- Wait for processing to complete.
- Download the text transcript.
- Review, correct, and format the text.
- Save and organise the final file.
Tips for Accurate Audio File Transcription
- Use high-quality source recordings
- Reduce background noise before uploading
- Avoid files with heavy overlapping speech
- Split very long audio files into smaller parts
- Select tools that perform well in your language
- Proofread names, numbers, and technical terms carefully
- Keep original audio files for reference
Factors That Influence Transcription Quality
| Factor | Effect on Accuracy |
|---|---|
| Background noise | Strong negative effect |
| Speaker clarity | Strong positive effect |
| Number of speakers | Moderate negative effect |
| Audio file quality | Moderate effect |
| Accent and speed | Moderate effect |
| Specialised vocabulary | Moderate negative effect |
Technical Settings That Affect Accuracy
| Setting | Recommendation for speech |
|---|---|
| Format | WAV or FLAC for best quality, MP3 or M4A for smaller files |
| Sample rate | 16 kHz or higher; many speech recognition models process audio at 16 kHz |
| Channels | Mono is usually fine; separate channels per speaker can help speaker identification |
| Bitrate (compressed files) | Avoid very low bitrates, which remove detail from voices |
| Volume | Consistent levels without clipping or distortion |
Recording at a higher quality than you need does no harm, but a recording made at too low a quality cannot be fixed later.
How Transcription Accuracy Is Measured
The standard measure is word error rate (WER). It compares an automatic transcript with a correct reference transcript and counts three types of errors:
- Substitutions: a wrong word in place of the right one
- Deletions: words that were missed
- Insertions: extra words that were not spoken
WER = (substitutions + deletions + insertions) ÷ number of words in the reference.
Example: if a 200-word reference passage has 6 substitutions, 3 deletions and 1 insertion, the WER is 10 ÷ 200, which is 5 percent, or roughly 95 percent accuracy.
For languages such as Japanese and Chinese, where words are not separated by spaces, character error rate (CER) is often used instead.
How to Run Your Own Accuracy Check
- Choose a representative two to five minute section of your audio.
- Transcribe it carefully by hand to create a reference.
- Run the same section through the tools you are comparing.
- Count substitutions, deletions and insertions, or use a free WER calculator.
- Pay special attention to errors in names, numbers and key terms, which matter more than small filler words.
Using Custom Vocabulary
Many tools allow you to add a list of words that the system should expect, such as:
- People’s names and company names
- Product names and brand terms
- Technical jargon and acronyms
- Place names
Adding these before transcription can noticeably reduce errors on the words that matter most. If your tool does not support custom vocabulary, use find and replace to fix repeated mistakes after transcription.
Free vs Paid Options for Transcribing Audio Files
Free tools are suitable for occasional use and shorter files. Paid services typically offer higher accuracy, faster processing, speaker labels, and better support. If you regularly transcribe audio files for work, a paid plan is usually more efficient.
Common Problems and Solutions
Low accuracy
Improve the source audio or try a different tool.
Long processing times
Split large files or use a faster paid service.
Missing speaker labels
Choose software that supports speaker identification and edit manually if needed.
File format issues
Convert the audio file to a widely supported format such as MP3 or WAV.
Expert Tips for Difficult Audio
- Slow playback to 0.75x when correcting fast speech.
- Use good headphones rather than speakers while editing.
- Mark unclear words with a consistent tag such as [inaudible 00:12:34] instead of guessing.
- Listen to difficult sections several times, then move on and return later with fresh ears.
- Ask participants or colleagues to confirm the spelling of names and specialist terms.
Common Audio and Video File Formats for Transcription
| Format | Type | Typical source | Transcription tips |
|---|---|---|---|
| MP3 | Compressed audio | Podcasts, downloads, many recorders | Widely supported; avoid very low bitrates |
| M4A (AAC) | Compressed audio | iPhone Voice Memos, many phone recorders | Widely supported; convert to MP3 if a tool rejects it |
| WAV | Uncompressed audio | Professional recorders, editing software | Best quality, but large files |
| FLAC | Lossless compressed audio | Archiving, high-quality recordings | Good quality with smaller size than WAV |
| OGG or OPUS | Compressed audio | Messaging apps, voice messages, some browsers | Check support; convert if needed |
| AMR | Compressed audio | Older phones, some call recordings | Often needs converting |
| MP4, MOV, WEBM | Video | Screen recordings, meetings, phone videos | Many tools accept video; otherwise extract the audio first |
How to Convert or Extract Audio
If your tool does not accept a file:
- Audacity (free, Windows, Mac and Linux) can open many audio formats and export to MP3 or WAV.
- VLC media player (free) includes a convert function that can extract audio from video files.
- Online converters are convenient, but avoid them for confidential recordings.
- Video editing apps can export the audio track only.
When converting speech, an MP3 at a moderate bitrate or a WAV file is usually a safe choice.
Dealing with Large Files
Many services set limits on file size or duration. If your file is too large:
- Compress it by exporting to MP3 at a lower but still clear bitrate.
- Convert stereo to mono, which roughly halves the size of uncompressed files and rarely affects speech recognition.
- Trim silence at the start and end.
- Split the file into parts with Audacity, keeping a few seconds of overlap so no words are lost at the joins.
- Transcribe each part, then combine the transcripts in order.
Transcript Output Formats Explained
| Output | What it contains | Use it for |
|---|---|---|
| TXT | Plain text | Notes, quick sharing, analysis |
| DOCX | Formatted Word document | Reports, editing, printing |
| Fixed layout document | Sharing a final version | |
| SRT | Numbered subtitles with start and end times | Video captions on most platforms |
| VTT | Web subtitles with timestamps | Online video players |
| CSV or JSON | Structured data with timestamps and speakers | Research, data analysis, developers |
Example of an SRT subtitle entry:
1
00:00:01,000 --> 00:00:04,000
Welcome to today's interview.
Each entry has a number, a time range and the text shown on screen.
Adding Timestamps and Speaker Labels
Timestamps let you jump to the exact point in the recording, which is useful for checking quotes or editing video. Speaker labels show who said what. Most tools add both automatically, but check:
- That speakers are separated correctly, especially when voices are similar
- That generic labels such as "Speaker 1" are replaced with real names
- That timestamp frequency suits your needs, such as every paragraph or every speaker change
Transcribing Audio Files on Different Devices
Computer: upload files to an online tool, use a desktop app such as a Whisper-based program, or use features in your office software where available.
iPhone: share an audio file from the Files or Voice Memos app to a transcription app, or use built-in transcripts in supported apps and languages.
Android: open the file in a transcription app, or use Google Recorder on Pixel phones for recordings made in that app.
Organising Audio Files and Transcripts
- Name files consistently, for example 2026-10-17_client-interview_smith.mp3.
- Save the transcript with the same name and a different extension, such as ".docx".
- Keep originals in a separate folder from edited or converted versions.
- Back up important recordings in at least two places.
- Delete files you no longer need, especially if they contain personal information.
- For large collections, keep a log of each file’s length, language, speakers and transcription status.
Choosing a Transcription Style for Research and Interviews
| Style | Includes | Common uses |
|---|---|---|
| Full verbatim | Every word, filler, pause, false start and non-verbal sound such as laughter | Conversation analysis, linguistics, legal records |
| Intelligent or clean verbatim | All meaningful speech, without fillers and repetition | Most qualitative research, journalism, business interviews |
| Edited transcript | Speech lightly rewritten for readability | Articles, reports and publications |
| Summary transcript | Key points rather than every word | Internal notes, quick customer insights |
| Annotated transcript | Speech plus notes on tone, gestures or context | Detailed qualitative studies |
Decide on the style before you start, and write your chosen conventions in a short style guide, for example how to mark pauses, overlapping speech, inaudible words and laughter, so every transcript is consistent.
A Simple Transcription Style Guide Template
- Speakers: Interviewer (I) and Participant (P1, P2 and so on)
- Inaudible speech: [inaudible 00:14:22]
- Uncertain words: [word?]
- Pauses: [pause] for noticeable silences
- Overlapping speech: [overlapping]
- Non-verbal sounds: [laughs], [sighs]
- Redactions: [name], [company], [location]
- Timestamps: at every change of speaker or every few minutes
Security and Privacy Considerations
Recording data often contains sensitive information. When transcribing:
- Use services with strong data protection policies
- Confirm where files are stored and for how long
- Avoid uploading highly confidential data to unknown free tools
- Consider on-premise or local processing for sensitive material
- Delete files from third-party services after transcription when possible
Research Ethics and Consent
For academic and professional research, transcription is part of handling personal data:
- Informed consent: participants should know they are being recorded, how recordings and transcripts will be used, who will access them and how long they will be kept.
- Data protection: in the UK and EU, personal data in recordings is covered by data protection law such as UK GDPR, so you need a lawful basis and appropriate safeguards.
- Ethics approval: universities and many organisations require approval before collecting recorded data, including the transcription method.
- Third-party services: check whether your ethics approval and data agreements allow audio to be uploaded to an external provider, especially one outside your region.
Anonymisation and Pseudonymisation
Removing identifying information protects participants:
- Anonymisation removes details so a person cannot reasonably be identified.
- Pseudonymisation replaces names with codes or pseudonyms, with a separate, secure key linking codes to real identities.
Practical steps:
- Replace names with codes such as P01 or pseudonyms.
- Remove or generalise employers, places, dates and unusual details.
- Keep the key linking codes to identities separate from the transcripts.
- Check whether a combination of small details could still reveal someone.
- Keep the original audio under stricter access controls than the anonymised transcript.
From Transcript to Analysis
Once transcripts are ready, researchers often import them into qualitative data analysis software such as NVivo, ATLAS.ti or MAXQDA for coding and theme development. To make this easier:
- Export transcripts in a format your software accepts, such as DOCX or TXT.
- Keep speaker labels and timestamps consistent.
- Use one file per interview, named with the participant code.
- Include a short header with the date, interviewer and session details.
Quality Control for Large Projects
| Stage | Check |
|---|---|
| Before transcription | Every file labelled, logged and backed up |
| After automatic transcription | Speaker labels correct, obvious errors fixed |
| Full review | Transcript compared with audio from start to finish |
| Spot check | A second person reviews random sections of several transcripts |
| Final | Anonymisation complete, files named and stored correctly |
Where your tool supports batch processing, use it rather than uploading files one at a time, and check a sample of transcripts from each batch rather than assuming all are equally accurate.
Estimating Time and Budget
Manual transcription usually takes several hours for every hour of audio, depending on the audio quality, the number of speakers and the style required. Automatic transcription is much faster, but you should still plan review time, typically longer for difficult audio or full verbatim transcripts. When budgeting for professional services, ask for quotes based on your total audio hours, required style, turnaround time and number of speakers.
Example Workflow: A 20-Interview Research Project
- Create a project log listing each interview's code, date, length and status.
- Record each interview on two devices as a backup.
- Upload recordings to an approved, secure transcription tool on the day of each interview.
- Correct the automatic transcript while the conversation is fresh.
- Apply the style guide and pseudonymise names and places.
- Ask a colleague to spot check two or three transcripts.
- Import the final transcripts into analysis software.
- Delete audio from the transcription service and store originals securely until the agreed deletion date.
Common File Problems and Fixes
- "Unsupported format" error: convert the file to MP3 or WAV.
- Transcript is mostly blank: the file may be silent on one channel or extremely quiet. Check the audio and normalise the volume.
- Wrong language detected: select the language manually before transcribing.
- Timestamps do not match: the file may have been trimmed after transcription. Transcribe the final version.
- Upload keeps failing: reduce the file size, use a wired connection or try a different browser.
Key Takeaways
- Transcribing audio files (音声ファイル 文字起こし) is fastest with AI-powered tools.
- Audio quality is the most important factor for good results.
- Always review and edit transcripts for important content.
- Both free and paid options are available depending on your needs.
- Organised transcripts improve documentation and productivity.
- Most tools accept MP3, WAV and M4A; convert unusual formats with free tools such as Audacity or VLC.
- Choose an output format to match the job: DOCX for documents, SRT or VTT for video captions.
- Measure accuracy with word error rate and agree a transcription style guide before large projects.
- For research recordings, check consent, ethics approval and anonymisation before uploading or sharing transcripts.
Frequently Asked Questions
What is the best way to transcribe an audio file?
Uploading the file to a reliable AI transcription service and then reviewing the output is the most efficient approach for most people.
Which audio file formats are supported?
Most tools accept MP3, WAV, M4A, and other common formats.
How long does it take to transcribe an audio file?
Many services process audio faster than real time. A 60-minute file often finishes in a few minutes.
Can I transcribe audio files for free?
Yes. Several tools offer free minutes or limited free plans, though paid options provide better accuracy and fewer restrictions.
Can I transcribe a video file directly?
Many transcription tools accept common video formats such as MP4 and MOV and extract the audio automatically. If your tool only accepts audio, use a free program such as VLC or Audacity, or your video editor, to export the audio track as MP3 or WAV before uploading.
What is an SRT file?
An SRT file is a plain text subtitle format. Each entry contains a number, a start and end time and the words to show on screen. Most video platforms, including YouTube, accept SRT files, so exporting a transcript as SRT is an easy way to add captions to your videos.
How do I transcribe an M4A file from my iPhone?
Most online transcription tools accept M4A, the format used by Voice Memos. Share the recording from Voice Memos or the Files app, save it to your computer or cloud storage, then upload it. If a tool rejects the file, convert it to MP3 using a free converter first.
Why does my audio file fail to upload?
Uploads usually fail because the file is too large, too long for the plan, in an unsupported format or the connection is unstable. Compress or split the file, convert it to MP3 or WAV and try again with a stable connection. Check the tool's stated limits before uploading long recordings.
Should I convert my audio file to WAV before transcribing?
Usually not. Converting a compressed file such as MP3 to WAV makes it larger but does not restore lost quality, so accuracy rarely improves. Convert only if your tool does not support the original format. If you are recording new audio, choosing WAV or a high-quality setting from the start is more useful.
What is the difference between verbatim and clean verbatim?
Full verbatim includes every word and sound, such as fillers, false starts, pauses and laughter. Clean or intelligent verbatim keeps all meaningful speech but removes fillers and repetition for readability. Most qualitative research and business interviews use clean verbatim, while linguistic and legal work often needs full verbatim.
Can I use AI transcription for research interviews?
Often yes, but check your ethics approval, consent forms and data agreements first. Some institutions require approved providers or local processing for personal data. If AI transcription is allowed, review every transcript carefully against the audio and anonymise it before analysis or sharing.
How do I anonymise an interview transcript?
Replace participants' names with codes or pseudonyms, then remove or generalise identifying details such as employers, places, dates and distinctive events. Keep the key linking codes to real identities in a separate secure location, and check that combinations of small details do not still reveal who someone is.
What is word error rate in transcription?
Word error rate (WER) is the standard way to measure transcription accuracy. It adds up substituted, deleted and inserted words, then divides by the number of words in a correct reference transcript. A lower WER means a more accurate transcript, so 5 percent WER is roughly 95 percent accuracy.
How long does it take to transcribe one hour of recording?
Manual transcription typically takes several hours per hour of audio, depending on audio quality, speakers and transcription style. Automatic tools produce a draft in minutes, but reviewing it properly against the recording still takes time, especially for full verbatim transcripts or noisy group discussions.
Should I keep the original recordings after transcription?
That depends on your consent forms, ethics approval and data retention policy. Many projects keep original audio securely until analysis is checked and then delete it on an agreed date, keeping only anonymised transcripts. Whatever you decide, tell participants in advance and follow the plan consistently.









Leave a Reply